H-AMR: The Next-Gen GRMHD Code

H-AMR is a massively scalable, GPU-accelerated general relativistic magnetohydrodynamics (GRMHD) code for black-hole accretion, jets, and explosive transients. It combines adaptive mesh refinement, local adaptive timestepping, and multi-level parallelism to concentrate resolution where the physics demands it while scaling across modern GPU clusters. Its high-performance design supports radiation transport, two-temperature plasmas, test particles, resistivity, neutrino transport, and realistic equations of state on exascale GPU clusters. Future development includes a Monte-Carlo radiation module that works at both low and high optical depths, and dynamical spacetimes.
H-AMR: Adaptive Mesh Refinement

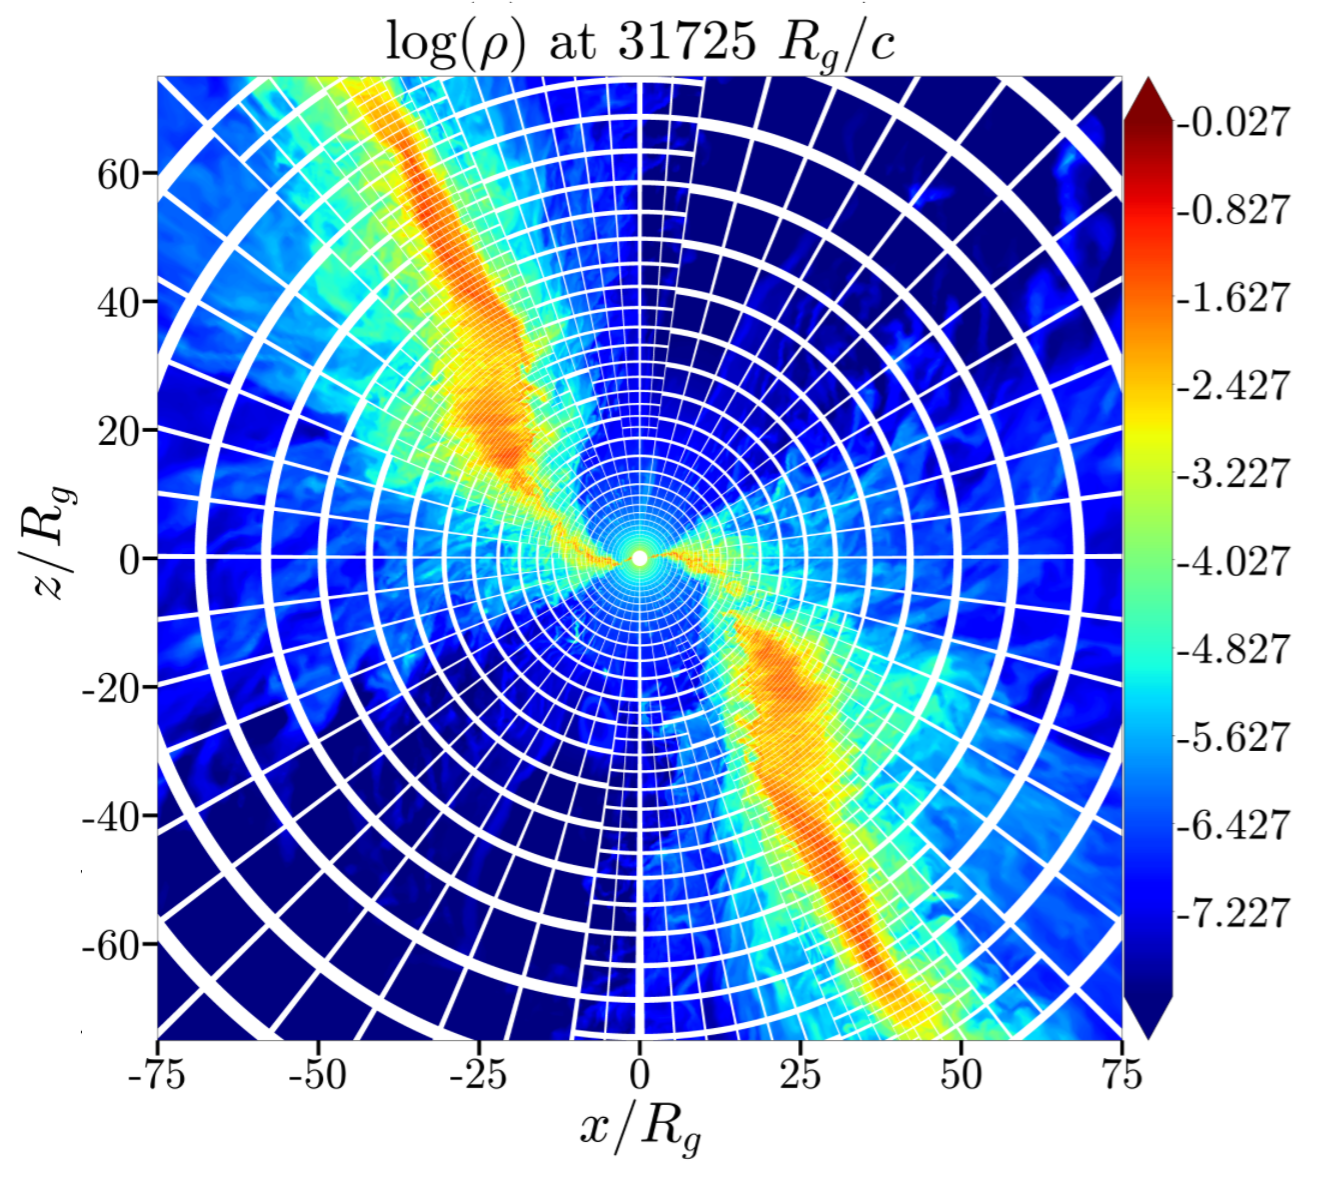
H-AMR uses adaptive mesh refinement (AMR) to place resolution where the dynamics demand it. The image shows the mesh around a warped accretion disk in an 80-billion-cell calculation on OLCF Frontier—the largest GRMHD simulation performed to date—run on more than 10,000 GPUs. Nested refinement follows the dense disk while avoiding unnecessary cost in the surrounding volume.

Local adaptive timestepping (LAT) complements AMR by allowing larger cells, especially at greater radii on the logarithmic grid, to advance with longer timesteps. This reduces the total number of updates, delivers a factor of 3–8 speedup, and can improve accuracy by reducing noise from repeated primitive-variable inversions.

H-AMR: Radiation, Neutrinos & Microphysics

H-AMR currently couples GRMHD to gray two-moment (M1) radiation transport, allowing radiation energy and momentum to feed back on the gas. We are now developing a Monte Carlo radiation module that follows individual photon packets and retains spectral and angular information, enabling predictive synthetic spectra, light curves, and images across optically thin and thick regimes.

For dense merger and collapsar disks, νH-AMR couples GRMHD to two-moment neutrino transport and a Helmholtz equation of state that captures ions, electron–positron pairs, radiation, and nuclear recombination. These ingredients determine cooling, electron fraction, neutronization, and the composition of outflows. Danat Issa’s simulations use this framework to follow binary mergers and identify when neutron-rich ejecta can support r-process nucleosynthesis of heavy elements.

grid (1).png

H-AMR: Treatment of Pole

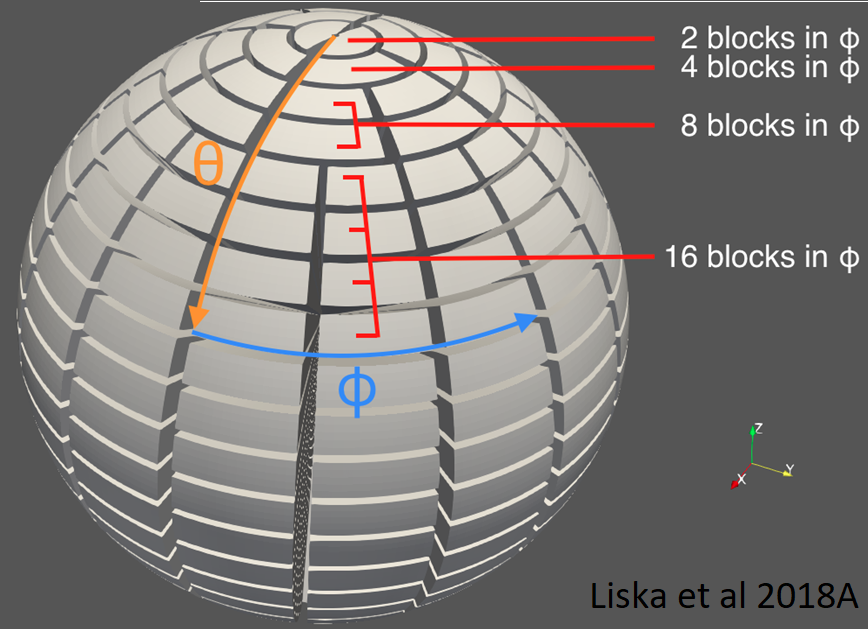
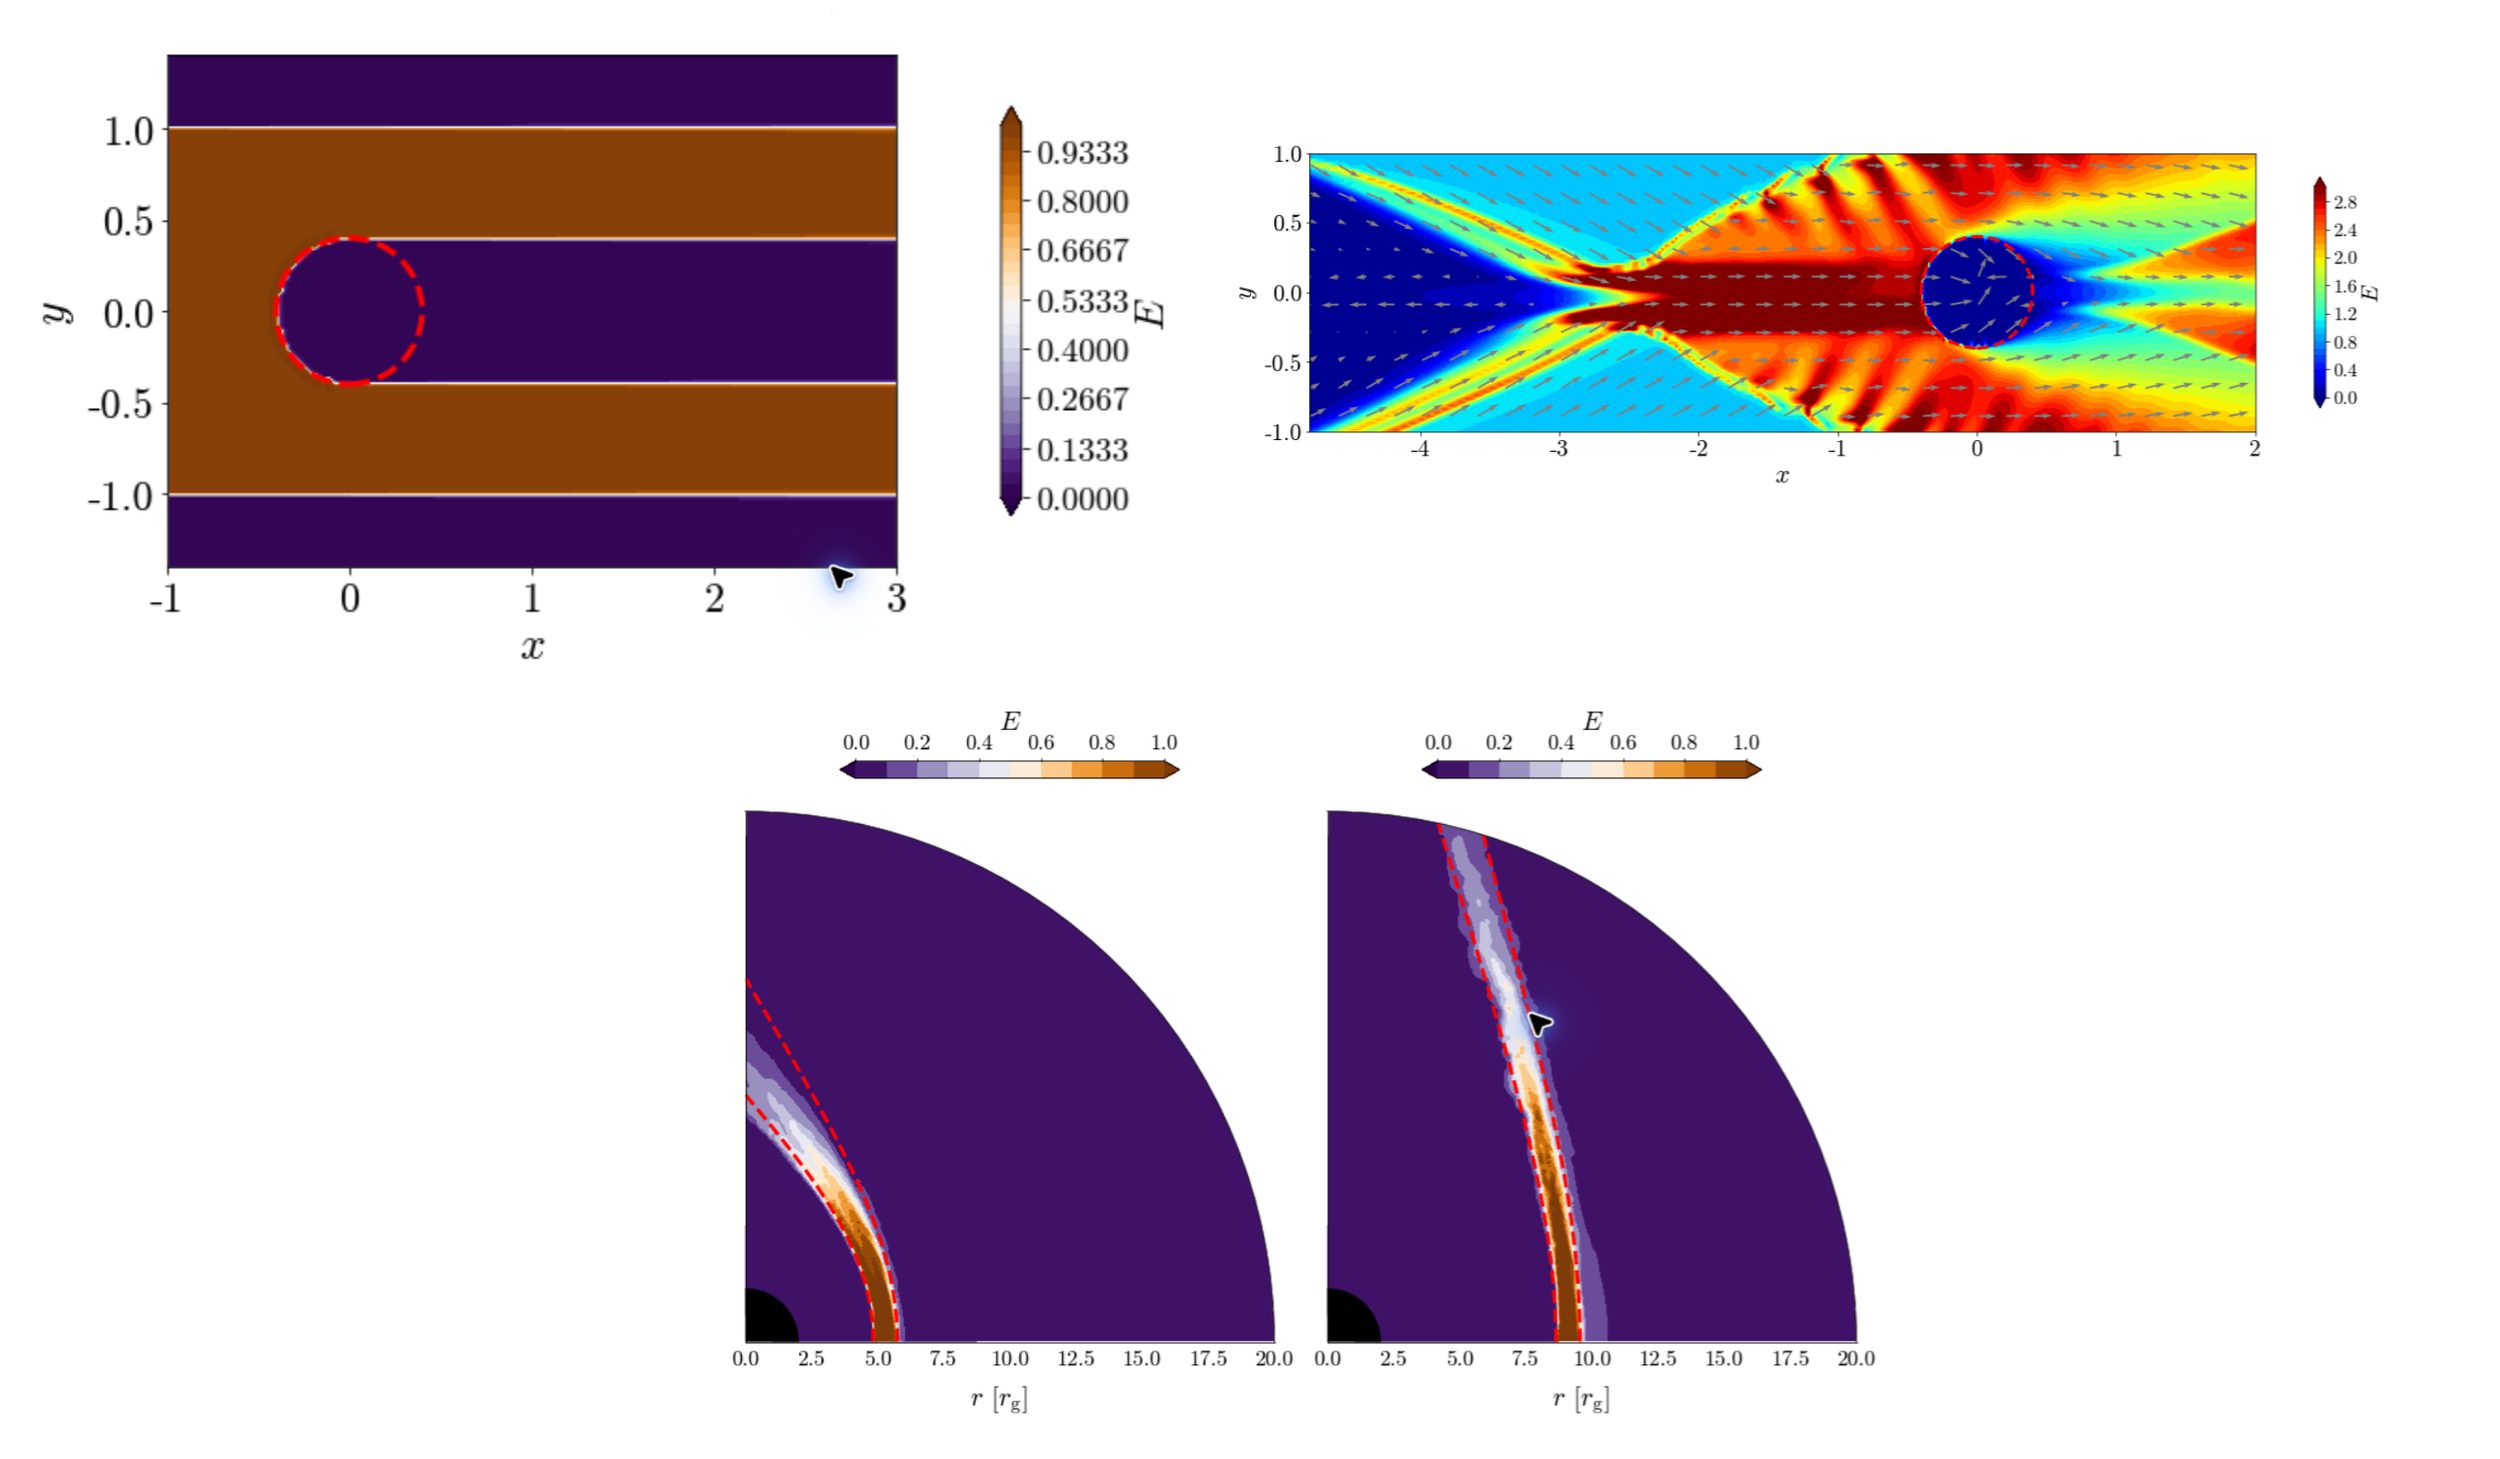
H-AMR efficiently and accurately handles the polar regions in a spherical grid. H-AMR achieves this by applying transmissive boundary conditions across the pole while using static mesh refinement (SMR) to avoid the squeezing of cells in the azimuthal direction, which would otherwise slow down computational speed by orders of magnitude. For this, H-AMR derefines the grid only in the troublesome azimuthal direction while maintaining the full resolution in the r- and theta-directions. This unique approach makes it possible to resolve features that pass close to the pole without slowing down the calculation.

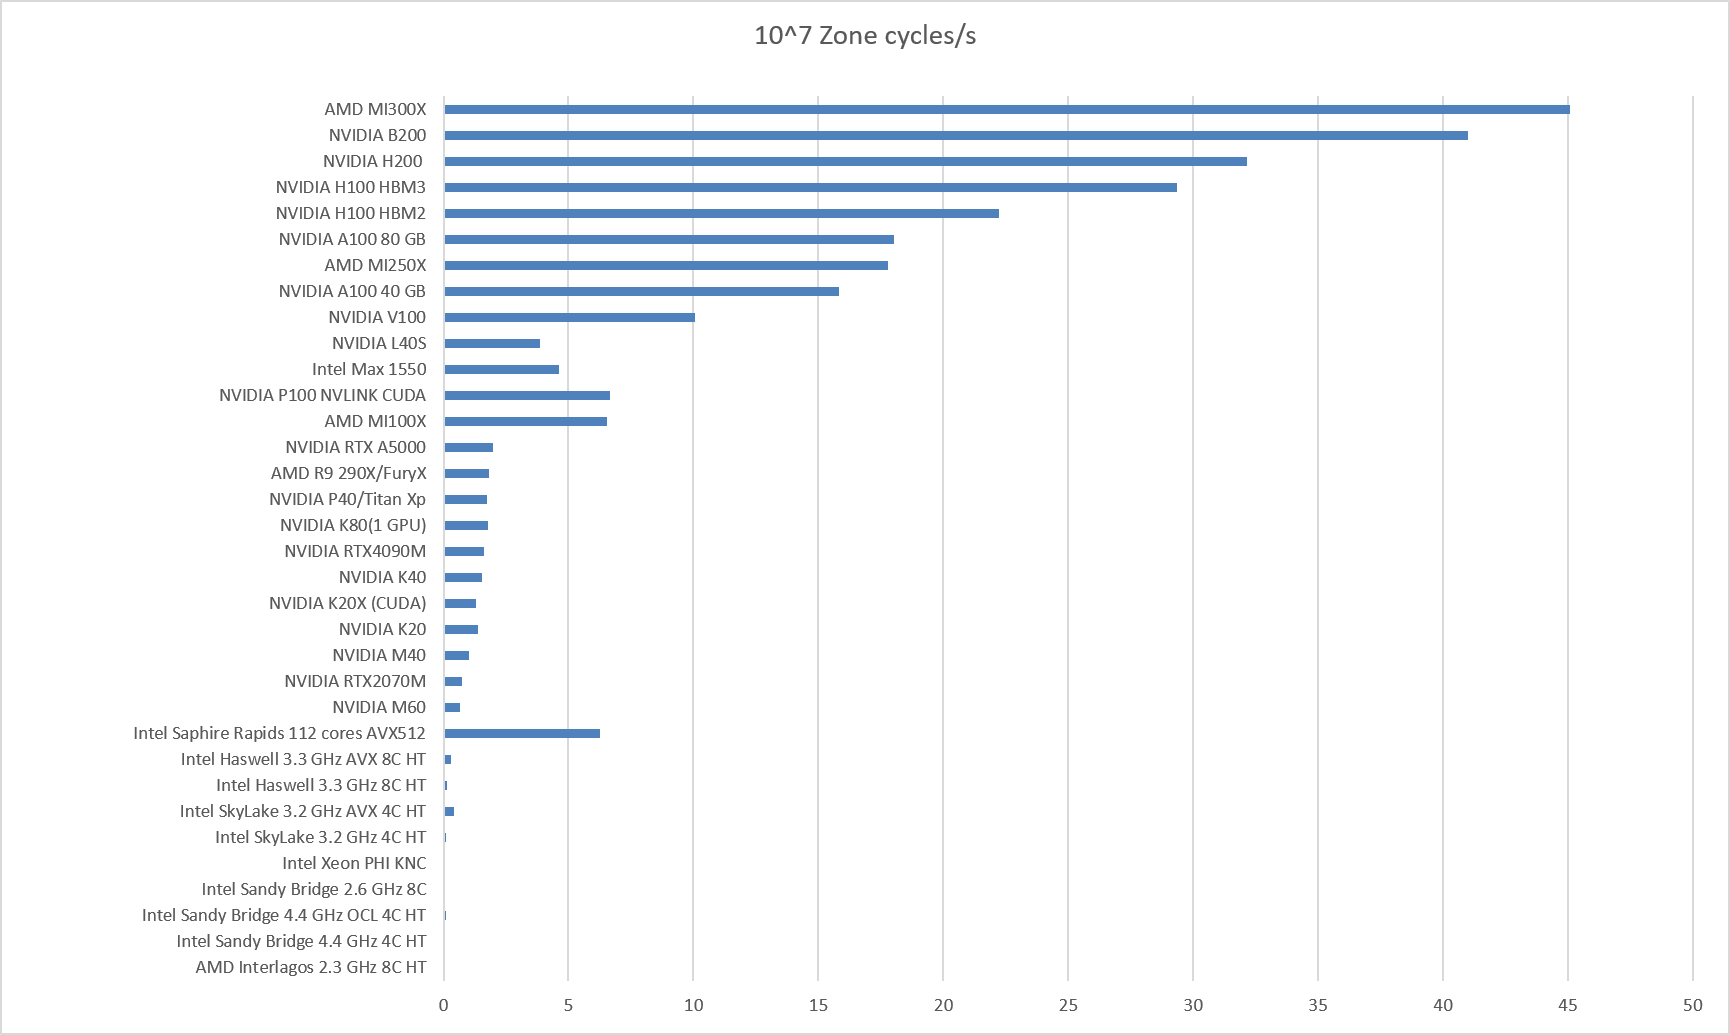
H-AMR single-device throughput across modern AMD, NVIDIA, and Intel GPUs and CPUs, measured in units of ten million zone cycles per second

H-AMR: Single CPU and GPU Benchmarks

H-AMR delivers high single-device throughput across several generations of accelerator hardware. In this non-radiative GRMHD benchmark, the AMD MI300X reaches about 4.5 × 10^8 zone cycles/s, followed by the NVIDIA B200 at roughly 4.1 × 10^8 and the H200 at 3.2 × 10^8. For comparison, the NVIDIA A100 reaches 1.6–1.8 × 10^8 zone cycles/s and the V100 about 1.0 × 10^8. The CPU measurements emphasize the large advantage of modern GPUs, which makes substantially larger and higher-resolution simulations practical.

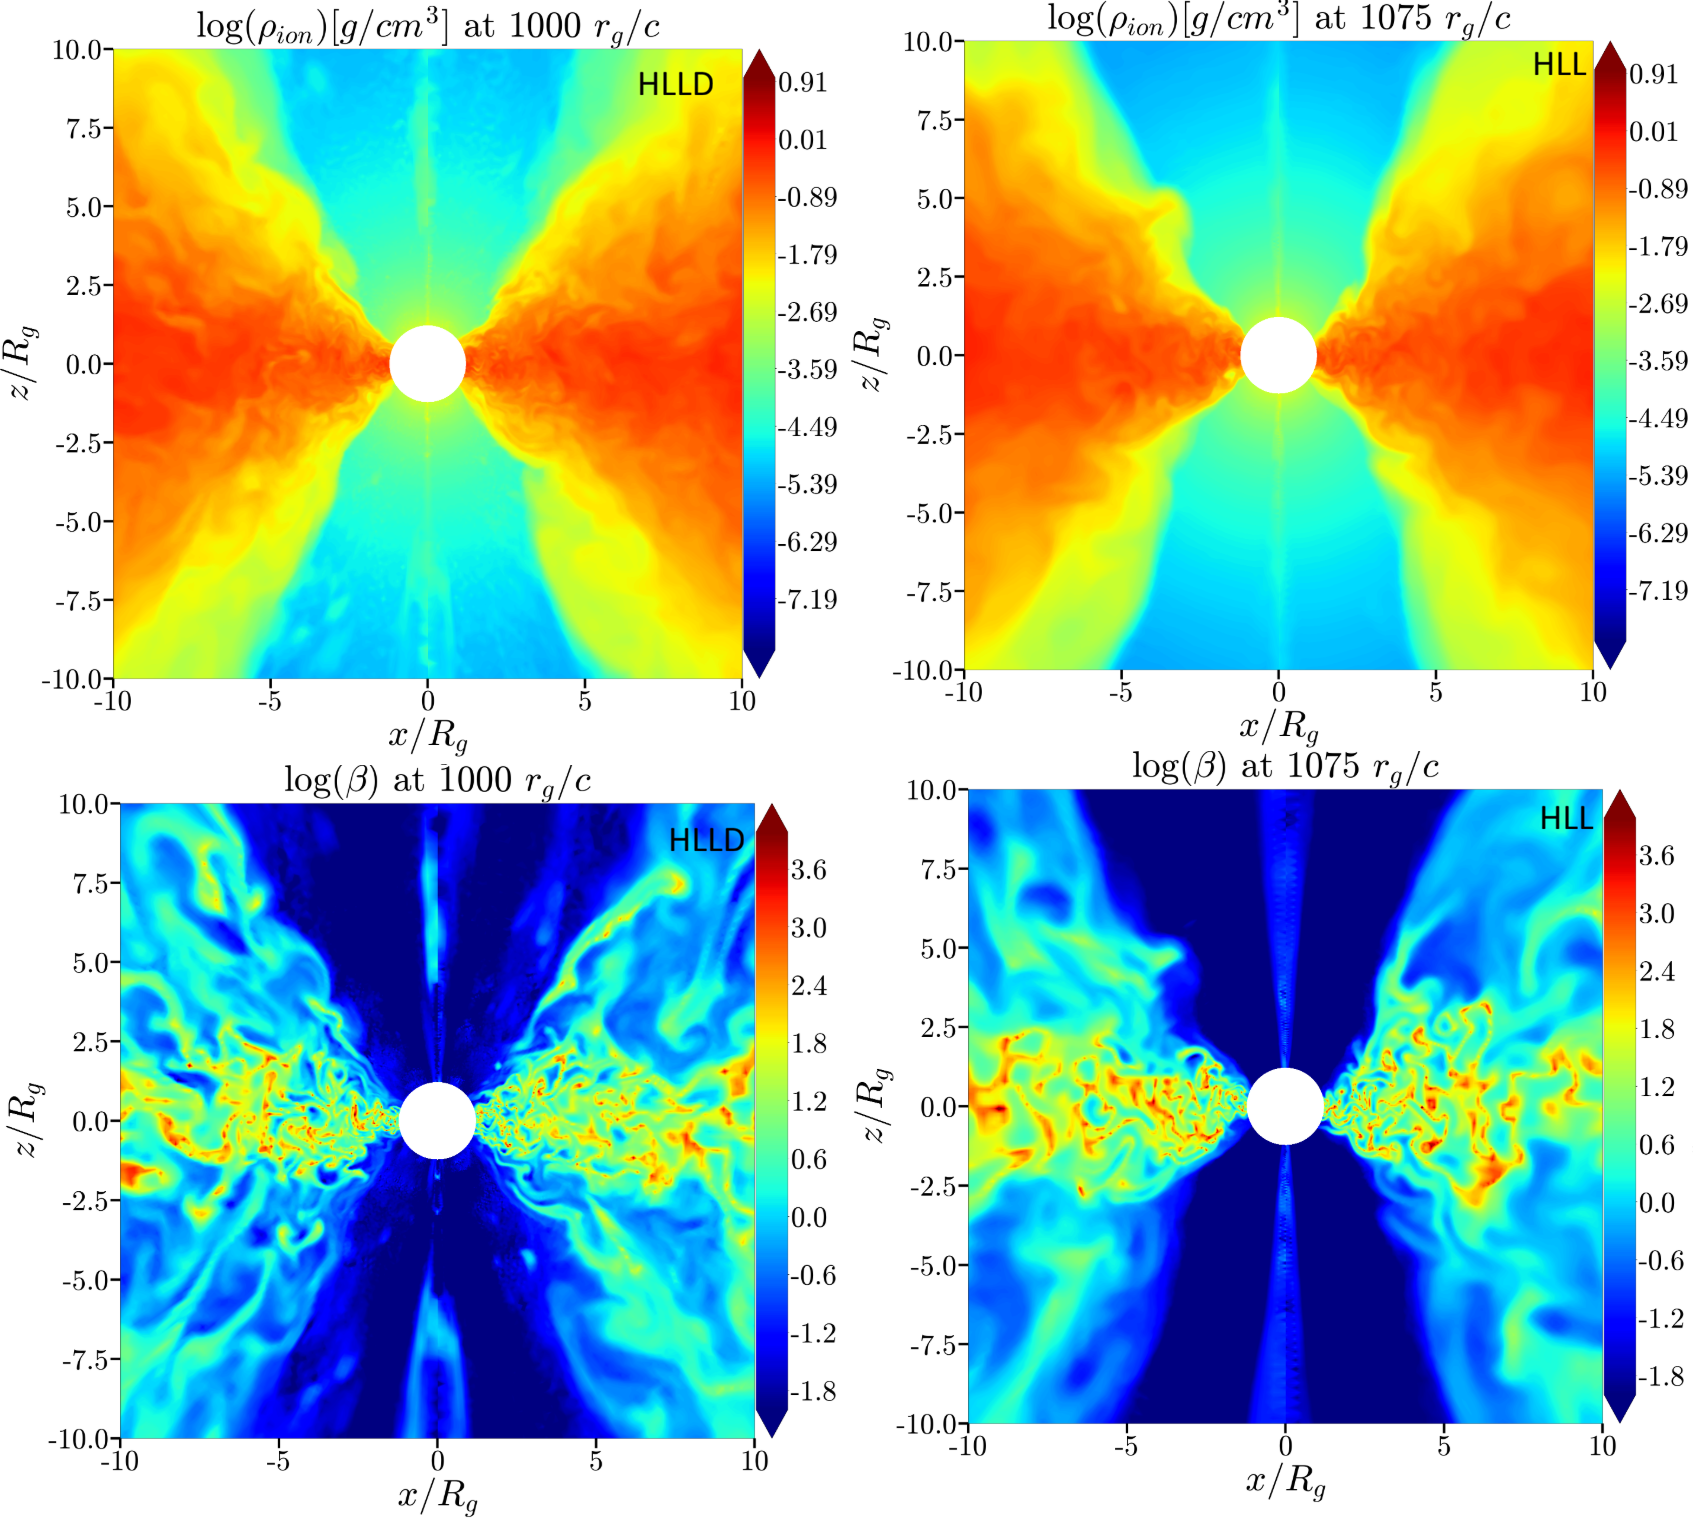
Comparison of relativistic accretion simulations using HLLD and HLL Riemann solvers, showing sharper turbulent density and plasma-beta structure with HLLD.

H-AMR: Advanced Riemann Solvers

H-AMR includes advanced approximate Riemann solvers for relativistic magnetohydrodynamics. The HLLD solver restores the contact discontinuity and Alfvén waves that are collapsed into the more diffusive HLL solution, preserving sharper disk structure and richer magnetized turbulence at a given resolution. The comparison at right shows the stronger small-scale density and plasma-beta structure captured by HLLD. Higher-order reconstruction and time integrators are also in development.

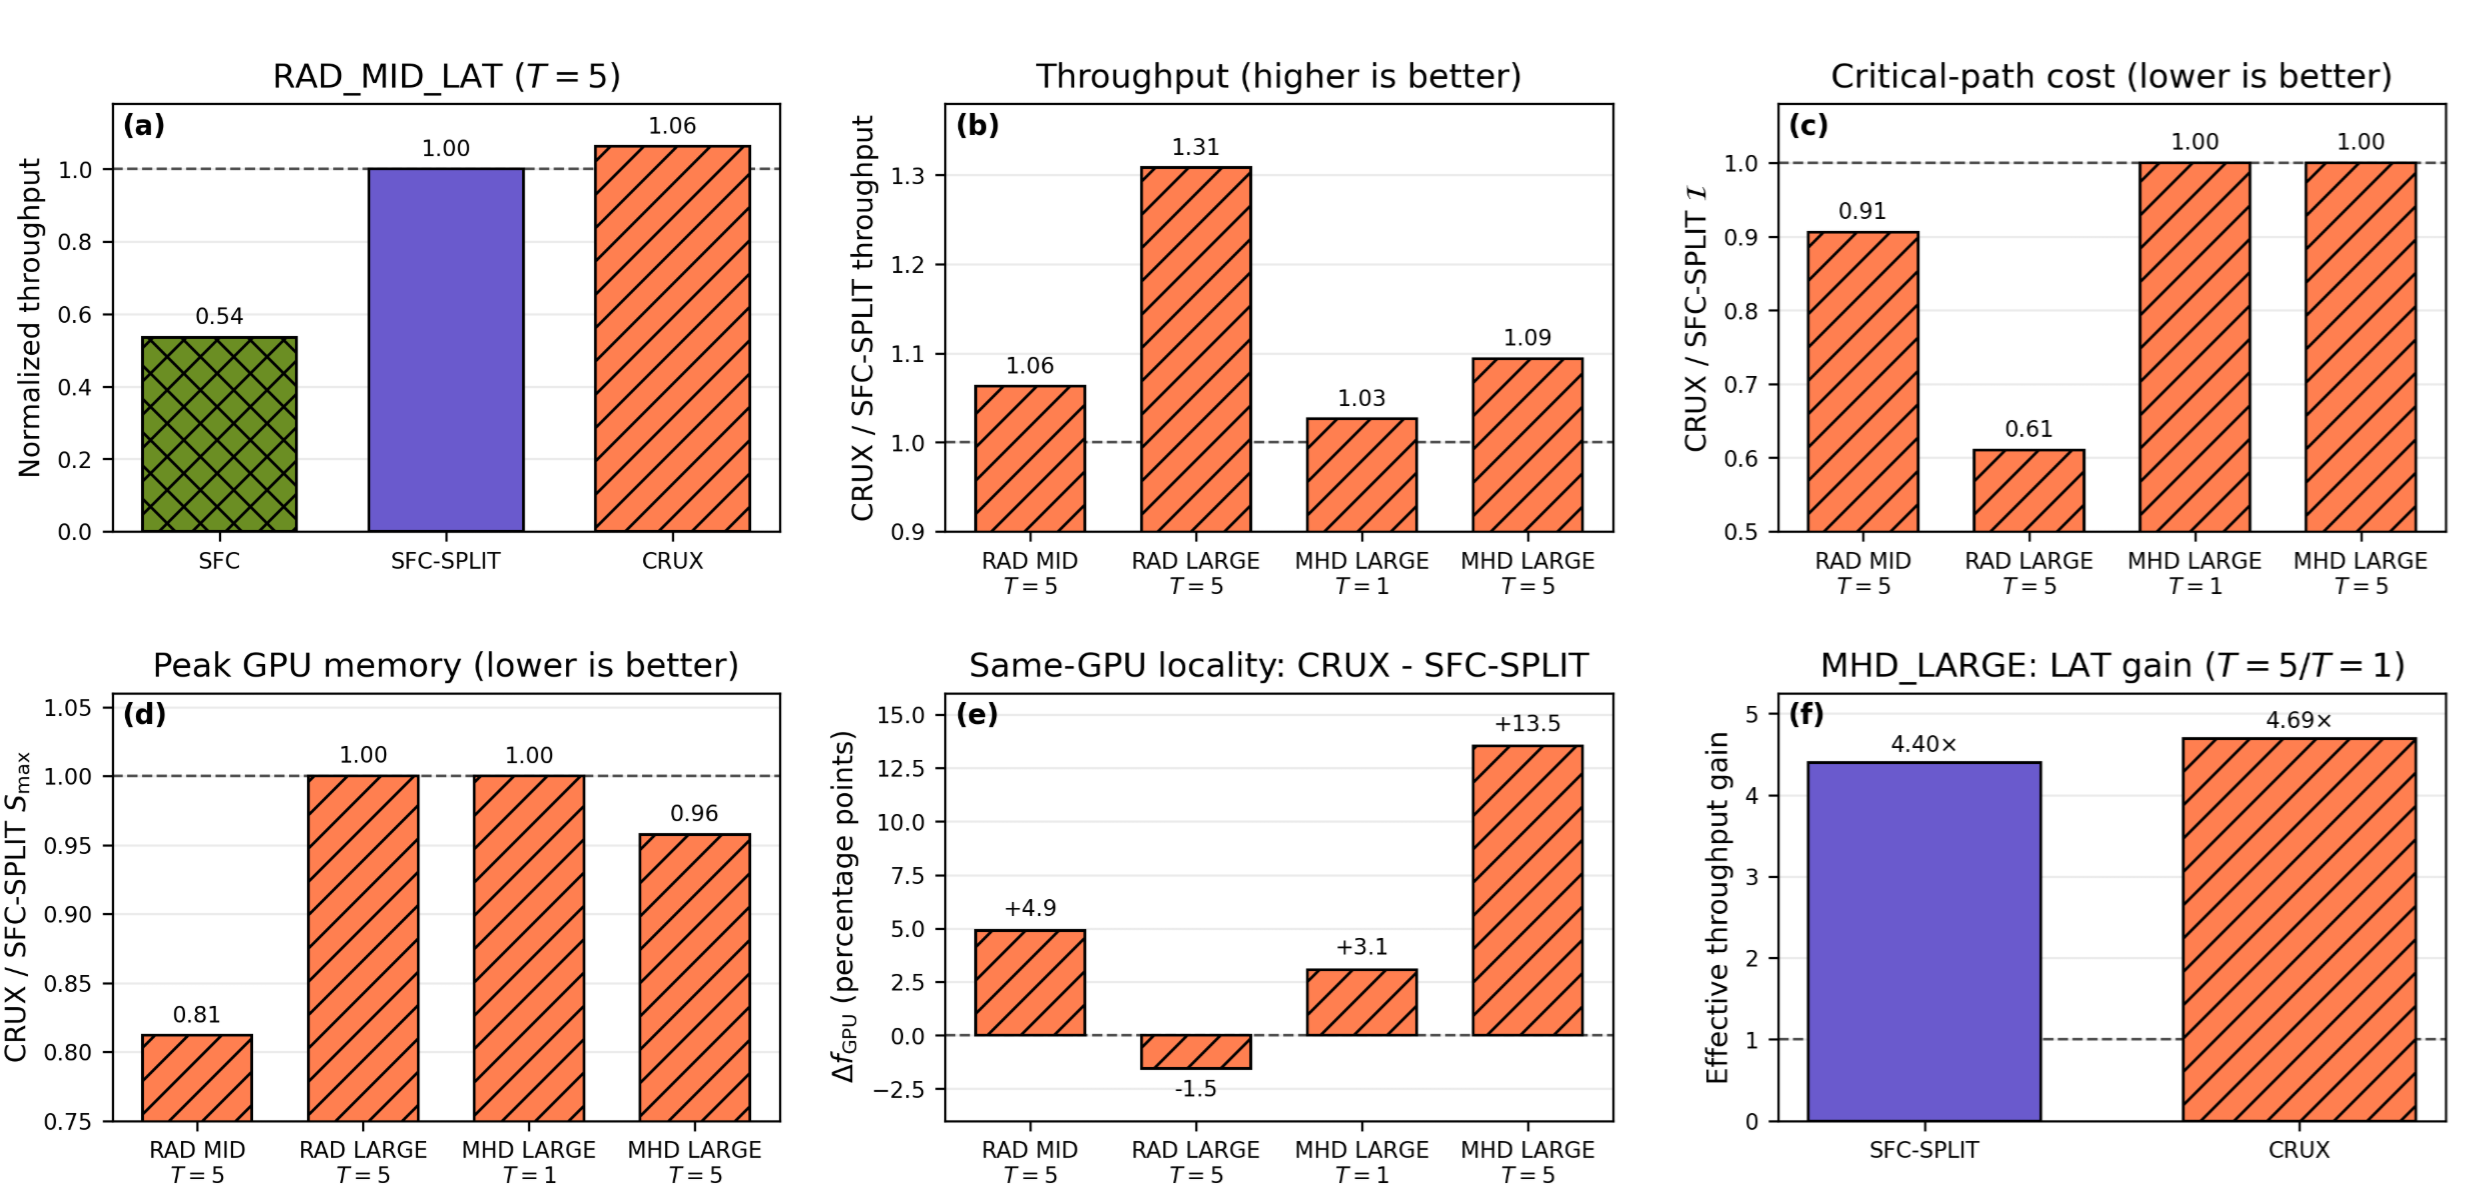
CRUX performance benchmarks across H-AMR workloads, including throughput, load balance, memory use, and communication locality

CRUX: Topology-Aware Load Balancing

CRUX is a topology-aware load balancer designed for the demanding, multiscale meshes used by H-AMR and other GPU fluid codes. It balances mesh blocks with different timestep costs while minimizing communication and accounting for heterogeneous hardware. Benchmarks on up to 5,400 GPUs on OLCF Frontier and ALCF Aurora show better load uniformity, memory use, and communication efficiency than space-filling-curve approaches.

Public Release

Presently, we are developing a novel Monte-Carlo radiation and test particle scheme to address accretion of high-luminosity black holes. Time constraints of the developers in the collaboration make it challenging to prepare and support a public release of H-AMR at the time of writing. However, we are looking forward to collaborate with other interested groups on topics of mutual interest. Please contact me for more details.

Publications

1) H-AMR: A New GPU-accelerated GRMHD Code for Exascale Computing With 3D Adaptive Mesh Refinement and Local Adaptive Time-stepping

2) The Event Horizon General Relativistic Magnetohydrodynamic Code Comparison Project

3) CRUX: A topology-aware load balancer for mesh-based fluid dynamics codes on GPU clusters

4) Magnetically-Driven Neutron-Rich Ejecta Unleashed: Global 3D Neutrino-GRMHD Simulations of Collapsars Probe the Conditions for r-process Nucleosynthesis

Next
Next

Warped Accretion Disks